Robots.txt is a small text file at yourwebsite.com/robots.txt that tells search engine crawlers which parts of your site they may crawl.
A simple robots.txt
User-agent: *
Disallow: /wp-admin/
Allow: /wp-admin/admin-ajax.php
Sitemap: https://www.example.com/sitemap.xml
What to block
- Admin and login areas.
- Internal search results pages.
- Cart and checkout pages, on stores.
- Staging or test folders.
What not to block
- CSS and JavaScript files Google needs to render pages.
- Images you want in Google Images.
- Any page you want to rank.
The most dangerous mistake
Disallow: / blocks your entire site. It is sometimes left over from development. Check yours today.
Robots.txt is not for hiding pages
Blocking a page in robots.txt does not guarantee it stays out of Google. To keep a page out of results, use a noindex tag and let Google crawl it. Read noindex explained.
AI crawlers
Some AI companies’ crawlers respect robots.txt rules. Decide whether you want to allow them; blocking them may affect visibility in some AI tools.
Create and test
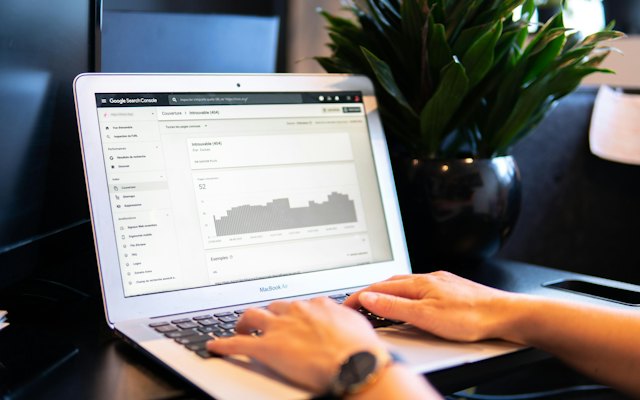
Build one with our robots.txt generator, and list your sitemap made with our sitemap generator. Check it in Search Console’s robots.txt report.
Want the full picture? This article is part of SEO: the complete guide, our in-depth guide with everything in one place.